This David Papkin page has info on AI (Artificial Intelligence).
Attention -the mechanism inside the transformer that does this comparing. For each word, it works out how much every other word should affect its meaning, and gives each one a weight.
Take the sentence “The bank approved the loan because it had strong collateral.” Attention is how the model works out that “it” means the loan and not the bank. It gives a strong weight to “loan” and “collateral” when interpreting “it.”
Bias testing means checking whether an AI system treats different groups of people unfairly or produces systematically skewed results.
For example, suppose an AI system is used to screen job applicants. Bias testing might compare its recommendations across gender, age, ethnicity, disability status, or other relevant groups to see whether one group is rejected much more often without a valid job-related reason.
It can involve checking:
- whether the training data under-represents certain groups,
- whether accuracy differs between groups,
- whether the model produces stereotyped or discriminatory outputs,
- and whether corrective measures reduce those differences.
Bias testing asks: “Does this AI work equally well and fairly for different groups of people?”
Deep learning is machine learning that uses multi-layer neural networks to automatically learn complex patterns from data. It is called “deep” because the neural network has many processing layers between the input and output. Input, hidden layers, output
For example, with image recognition:
- Early layers may detect edges and colors
- Middle layers may detect shapes and textures
- Deeper layers may recognize eyes, faces, cars, animals, etc.
Deep learning is used in things such as ChatGPT and other LLMs, speech recognition, image recognition, translation, autonomous driving, and medical image analysis.
Embedding – a model can convert text into an embedding, which is basically a long list of numbers representing its meaning.
Foundation model -is a large, general-purpose model trained once on a huge, broad dataset of text, code and sometimes images. It is then adapted to many different tasks instead of a new model being built for each one. Examples are GPT-4, Claude, Gemini and Llama.
The old approach was one model per job: one for fraud, one for document classification, one for chatbots, each trained from scratch. A foundation model reverses that. You build one general model and adapt it in one of three ways:
- Prompting: tell it what to do.
- RAG: give it your documents at the moment you ask.
- Fine-tuning: retrain it slightly on your own examples.
Grounded answer is an AI response supported by trusted source data or retrieved documents.
Inference is the stage where a trained AI model is actually used to make a prediction or generate an answer.
simple way to think about it:
Training = learning
Inference = using what was learned
For example, with ChatGPT:
- During training, the model learns patterns from large amounts of data.
- During inference, you type a question and the model generates a response.
For image recognition:
- Training: the model learns from many labeled cat and dog images.
- Inference: you show it a new image and it predicts “cat.”
In an LLM system, the flow is roughly:
Prompt → model inference → generated response
Neural Network – a machine-learning model inspired loosely by the way neurons in the brain process signals. It is made of connected units called artificial neurons, usually arranged in layers:
Input layer → Hidden layer(s) → Output layer
For example, for recognizing a cat:
- Input layer: receives image pixels
- Hidden layers: learn patterns such as edges, ears, eyes, fur
- Output layer: predicts “cat” or “not cat”
Each connection has a weight. During training, the network adjusts those weights to reduce errors and improve its predictions.
Goal – recognize Circle
Wrong prediction, needs to be trained
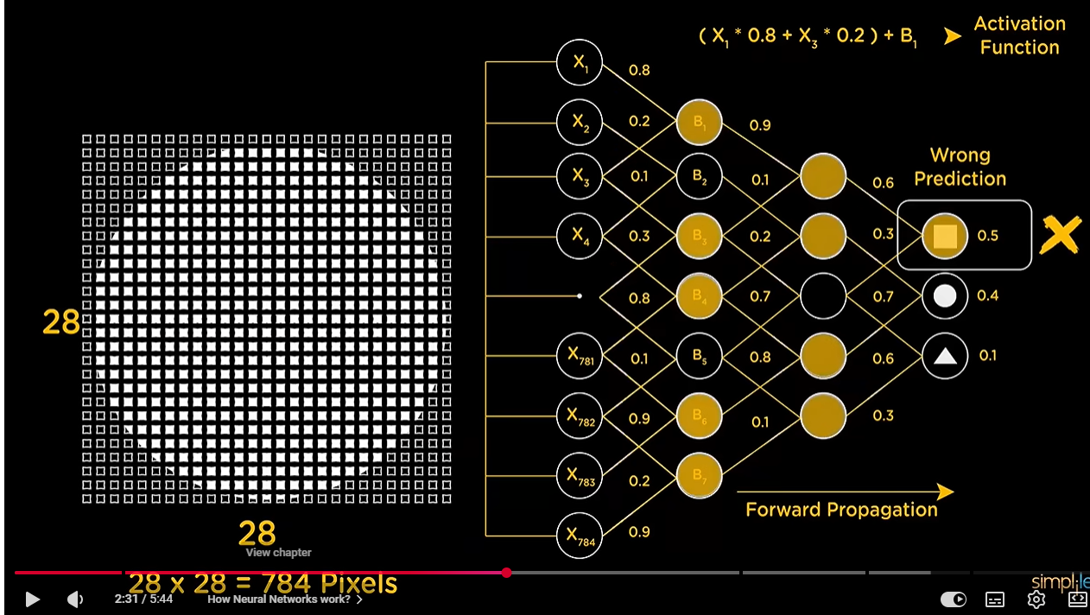
Neurons that learn patterns by adjusting weights during training.
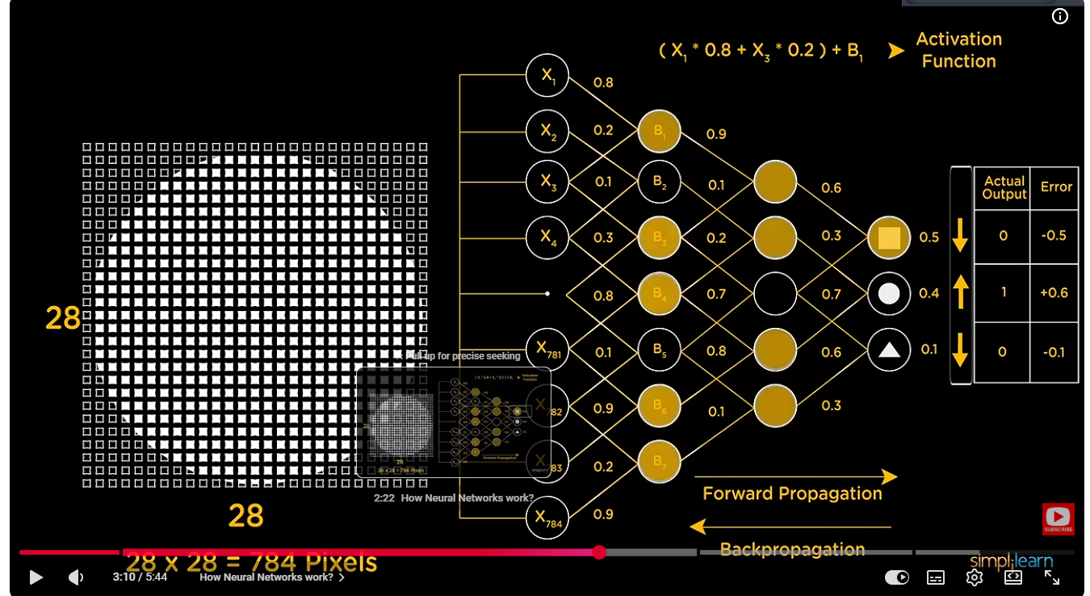
And the relationship is:
AI → Machine Learning → Neural Networks → Deep Learning
Deep learning simply means using neural networks with many layers.
Prompt injection – is when someone hides instructions inside text an AI reads, and the AI follows those hidden instructions instead of (or as well as) the ones its owner gave it.
RAG (Retrieval-Augmented Generation) – an AI technique that retrieves relevant external information and gives it to a language model so it can produce more accurate, grounded answers instead of relying only on what the model learned during training.
parameter – a number inside the neural network that controls how strongly one thing influences another.
For example, imagine a tiny model deciding whether the word “bank” is related to “money.”
It might have a learned weight like:
money → bank = 0.82
That 0.82 could be one parameter. A higher value means a stronger learned connection; a lower or negative value could mean a weak or opposite relationship.
Real LLMs have enormous matrices containing billions of numbers like:
0.82, -0.17, 1.04, 0.003, …
During training, the model adjusts these numbers so it becomes better at predicting the next token.
So, in simple terms: a parameter is one learned numerical setting inside the model.
tokenizer converts human-readable text into tokens that an LLM can process. Please remember: one token is not always one word. It can be a whole word, part of a word, punctuation, or other text fragments.
For example:
“I like networking.”
might be split into:
“I” | “ like” | “ network” | “ing” | “.”
Those tokens are then converted into numbers that the neural network can work with.
So the flow is:
Text → Tokenizer → Tokens → LLM
Different LLMs do not necessarily use the same token sizes. In fact, even within the same LLM, tokens can have different lengths.
A token can represent:
-
A single character
-
Part of a word
-
An entire word
-
A punctuation mark
-
A space combined with a word
Example: How LLMs tokenize text
Consider the word “unbelievable”.
| Tokenizer | Possible breakdown |
|---|---|
| Tokenizer A | un + believable |
| Tokenizer B | unbeliev + able |
| Tokenizer C | un + believ + able |
Illustrative examples, not actual output from specific models.
Why do token sizes differ?
Different LLMs use different tokenizers and vocabularies.
| LLM family | Tokenization approach |
|---|---|
| OpenAI GPT | BPE-based tokenizers |
| Meta Llama | BPE-based tokenizers |
| Google Gemini | Uses its own tokenizer |
| Anthropic Claude | Uses its own tokenizer |
Even models using Byte Pair Encoding (BPE) may split the same sentence differently because their vocabularies and training processes differ.
Important distinction
Token size vs. context window size
-
Token size: How much text an individual token represents.
-
Context window: How many tokens the model can process in one interaction.
For English text, a commonly used OpenAI approximation is:
1 token ≈ 4 characters
Or approximately ¾ of an English word
This is only an average, not a fixed rule. Other languages and technical text can have very different token counts.
Testing tools
| Tool | Banking / Insurance Use |
|---|---|
AI Verify Toolkit (incorporating MAS Veritas) |
AI governance evaluation, fairness, explainability and transparency assessments, including financial-sector FEAT principles (Fairness, Ethics, Accountability and Transparency). |
Amazon Bedrock Guardrails |
Runtime AI safety controls: content filtering, personally identifiable information (PII) protection, prompt-injection detection and grounded-answer validation for banking and insurance chatbots. |
Arize Phoenix |
LLM tracing, evaluation and troubleshooting for AI-powered banking and insurance applications. |
DeepEval |
Automated evaluation of accuracy, hallucinations, bias and response quality in financial AI assistants. |
Fiddler |
Fraud detection model monitoring, data drift, performance tracking and production AI observability. |
Garak |
LLM security scanning, vulnerability assessment, prompt-injection and adversarial testing. |
Giskard |
Detection of chatbot hallucinations, security vulnerabilities and reliability issues in financial customer-service assistants. |
LangSmith |
LLM evaluation rubrics, tracing, human reviewer feedback and continuous quality improvement. |
Microsoft Foundry |
Groundedness, relevance, content safety and quality evaluation of AI solutions using Microsoft Azure. |
Promptfoo |
Automated prompt evaluation, adversarial testing, red teaming and prompt-injection security testing. |
Ragas |
Evaluation of retrieval-augmented generation (RAG), answer faithfulness and accuracy of retrieved insurance policies and banking documents. |
Vector database (vector DB) is a database designed to store and search vectors—numerical representations of things like text, images, audio, or documents.
In AI, a model can convert text into an embedding, which is basically a long list of numbers representing its meaning.
For example:
“How do I reset my password?”
might become something like:
[0.12, -0.44, 0.81, 0.07, ...]
A vector database stores these embeddings and can quickly find other vectors that are similar in meaning, not just exact keyword matches.
For example, if your database contains:
- “Change your account password”
- “Reset forgotten login credentials”
- “Configure a Cisco router”
and you search for “I forgot my password”, the vector DB will likely retrieve the first two because they are semantically similar.
This is especially important in RAG — Retrieval-Augmented Generation:
Documents → embeddings → vector database → similarity search → relevant chunks → LLM → answer
So if you upload 1,000 company manuals, the AI does not normally send all 1,000 manuals to the LLM. It searches the vector DB for the most relevant sections and sends only those sections to the model.
Common vector databases include Pinecone, Milvus, Weaviate, Qdrant, Chroma, and vector-search features in databases such as PostgreSQL with pgvector and cloud AI search services.
Update cadence -AI models can change over time, so organisations need to know how often the model is updated, whether behaviour may change after an update, and how customers are notified.
AI links
Attention is all you need – is a 2017 research paper on machine learning authored by eight scientists and engineers working at Google. The paper introduced a new deep learning architecture known as the transformer, based on the attention mechanism proposed in 2014 by Bahdanau et al.[2]
AI videos
AI Agents
AI Agents, Clearly Explained
https://youtu.be/FwOTs4UxQS4
Artificial Intelligence
What Is AI and How Does It Work? Artificial Intelligence Explained Simply in 1 Minute
https://www.youtube.com/watch?v=3lCXy26UeD8
AI Hallucinations
How AI Hallucinates (& Why ChatGPT, Gemini & Claude Get Things Wrong) | AI Hallucination Explained
https://www.youtube.com/watch?v=3WPSTvYRM2Y
How AI Learns
How Does AI Learn From Data? The Truth Behind ChatGPT, Claude, Machine Learning & Neural Networks
https://www.youtube.com/watch?v=lkqu63xCxkQ
Deep Learning
Deep Learning | What is Deep Learning? | Deep Learning Tutorial For Beginners | 2026 | Simplilearn
https://www.youtube.com/watch?v=6M5VXKLf4D4
Fine-Tuning
How to Fine-Tune Any LLM in 10 Minutes (Unsloth Studio Tutorial)
https://youtu.be/50XUr1-PbUk
Generative AI
Generative AI Explained In 5 Minutes | What Is GenAI? | Introduction To Generative AI | Simplilearn
https://youtu.be/NRmAXDWJVnU
Machine Learning
All Machine Learning Models Explained in 5 Minutes | Types of ML Models Basics
https://youtu.be/yN7ypxC7838
Neural Networks
Neural Network In 5 Minutes | What Is A Neural Network? | How Neural Networks Work | Simplilearn
https://www.youtube.com/watch?v=bfmFfD2RIcg
RAG — Retrieval-Augmented Generation
What is Retrieval-Augmented Generation (RAG)?
https://www.youtube.com/watch?v=T-D1OfcDW1M
RAG vs Fine-Tuning vs Prompt Engineering
RAG vs Fine Tuning vs Prompt Engineering
https://youtu.be/Q-_D_2NWECE
Security issues
The Hugging Face story is even scarier than we thought – YouTube
Prompt Injection
Quick summary on prompt injection(CatGPT)
Prompt Injection Explained (Arjay McCandless)
OWASP Top 10 for Agentic AI 2026 Explained | AI Agent Security | Full overview
How LLM jailbreaking can bypass AI security with multi-turn attacks – Crescendo LLM Jailbreak
Tokenization
What Is Tokenization in AI
https://youtu.be/62EPf7d4jxA
Tokens, Context Windows & Transformers
How AI Remembers Context (It’s Not Memory!) | Context Windows, Tokens & Transformers Explained
https://www.youtube.com/watch?v=2fFXw0lO9sE
End of David Mark Papkin AI page.
David Papkin favorite movies